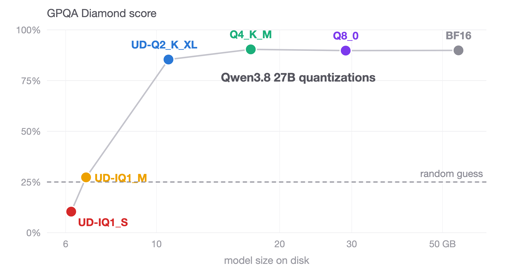
I test Unsloth GGUFs of Qwen3.8 27B (Q4_K_M, UD-Q2_K_XL, UD-IQ1_S) with llama.cpp on GPQA Diamond, IFBench, Terminal-Bench 2.1. Q4_K_M matches BF16 abd fits an RTX 4090.
What software are you using for your inference server (llama.cpp, ollama, vllm, sglang, etc)? There are quite a few published recipes that should get you where you want to go.
In particular, I think you want at least the following flags to limit the context length and quantize the Key and Value caches (full context is 16GB alone at full precision KV):
-c 65535
–cache‑type‑k q8_0 --cache‑type‑v q8_0
Using q8_0 for Key and Value cuts that in half. So native full context of 262,144 tokens costs 8 GiB instead of 16, but to fit on one card, something like 65535 would only add 2 GB of VRAM at Q8 KV, respectively. I have also heard good things about using q4_0 for KV, which would cut the context budget by half again, with less than 2% loss.
Thanks. I did get it working on the 3090 alone with reduced context and KV cache quantized to 4 bits, but it was getting itself muddled up and going round in circles more. Once I got it up to the full 262K context and 8-bit KV cache, it seemed noticeably less confused and more useful, but it needed the extra 10GB for that.


So I heard, but I couldn’t get it to fit. I’m really fumbling my way around this stuff so it’s possible I’m just not doing it right.
What software are you using for your inference server (llama.cpp, ollama, vllm, sglang, etc)? There are quite a few published recipes that should get you where you want to go.
It’s llama.cpp. If you know where I could find those recipes I’d appreciate a link.
They’re posted on GitHub pretty regularly, here’s one for the 3090/A5000 specifically.
https://github.com/mikecovlee/qwen3.8-27b-24gb-recipe
In particular, I think you want at least the following flags to limit the context length and quantize the Key and Value caches (full context is 16GB alone at full precision KV):
-c 65535 –cache‑type‑k q8_0 --cache‑type‑v q8_0
Using q8_0 for Key and Value cuts that in half. So native full context of 262,144 tokens costs 8 GiB instead of 16, but to fit on one card, something like 65535 would only add 2 GB of VRAM at Q8 KV, respectively. I have also heard good things about using q4_0 for KV, which would cut the context budget by half again, with less than 2% loss.
Thanks. I did get it working on the 3090 alone with reduced context and KV cache quantized to 4 bits, but it was getting itself muddled up and going round in circles more. Once I got it up to the full 262K context and 8-bit KV cache, it seemed noticeably less confused and more useful, but it needed the extra 10GB for that.
Someone reported q5_1 having indistinguishable results from q8 for kV cache up to 130k IIRC. You could give it a try.